

Bringing Your Muse to Life
Today, we’re introducing Muse Realtime Avatar, our state-of-the-art embodiment technology that turns Muse Realtime Voice into expressive, interactive avatars.
Conditioned on reference media, Muse Realtime Avatar brings any character into a live conversation. A photographic portrait responds through subtle expressions, while a full-body illustration gestures and shifts posture as it speaks. Animals and everyday objects become expressive without losing what makes them distinctive. Frame by frame, the avatar’s appearance and mannerisms remain coherent from one conversational turn to the next.
Beyond talking heads, Muse Realtime Avatar brings any image to life in real time, with expressive facial, hand, and full-body movement.
From Intelligence to Real-Time Presence
Muse Realtime Voice and Muse Realtime Avatar form a single streaming system connecting intelligence, voice, and embodiment. Muse Realtime Voice provides the conversational intelligence and produces a stream of speech tokens (VQs) carrying both what is said and how it’s delivered. An audio decoder turns those tokens into speech, while Muse Realtime Avatar consumes the same stream to generate the corresponding visual performance. Sharing this token stream keeps voice, lip motion, and expression synchronized.
Muse Realtime Avatar is an audio-driven, Diffusion Transformer conditioned on speech-token stream, reference media, and a rolling window of recent video latents. It generates video in short causal chunks. As each chunk completes, its newest generated latents become motion context for the next, carrying the avatar’s appearance and mannerisms forward while keeping the computation bounded, allowing the generation to continue for as long as the conversation does.
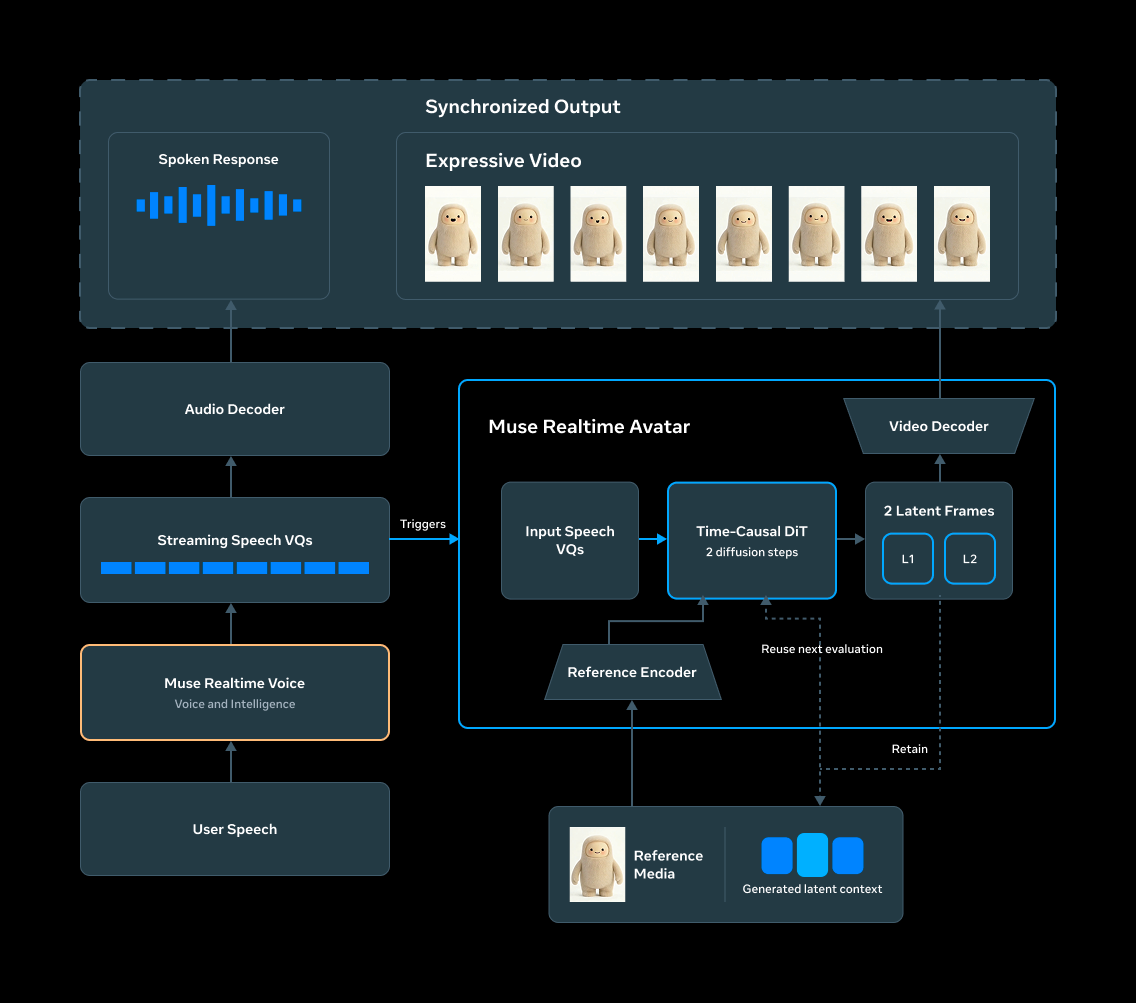
Muse Realtime Avatar turns streaming speech VQs into synchronized video, carrying generated context forward to maintain continuity throughout the conversation.
Real-Time Infinite Video Generation
Live streaming must solve two problems at once: generating video fast enough for real-time interaction and remaining visually consistent throughout the conversation without accumulating errors.
We begin with a high-quality bidirectional teacher and produce a causal student with a fixed-length KV cache through self-forcing and distribution matching distillation. Self-forcing allows the student to train on its own generated context and teaches it to resist drift as small errors accumulate over time, matching the conditions it encounters during inference.
The teacher uses 40 diffusion steps with three-way classifier-free guidance (CFG), requiring three model passes per step and totaling 120 model evaluations per chunk. Our carefully tuned recipe jointly distills the diffusion process and the effect of CFG into an unguided two-step student. Together, these techniques allow the student to reproduce in two unguided evaluations what the teacher progressively refines over 120 guided evaluations, a 60x reduction, while closely preserving teacher quality.
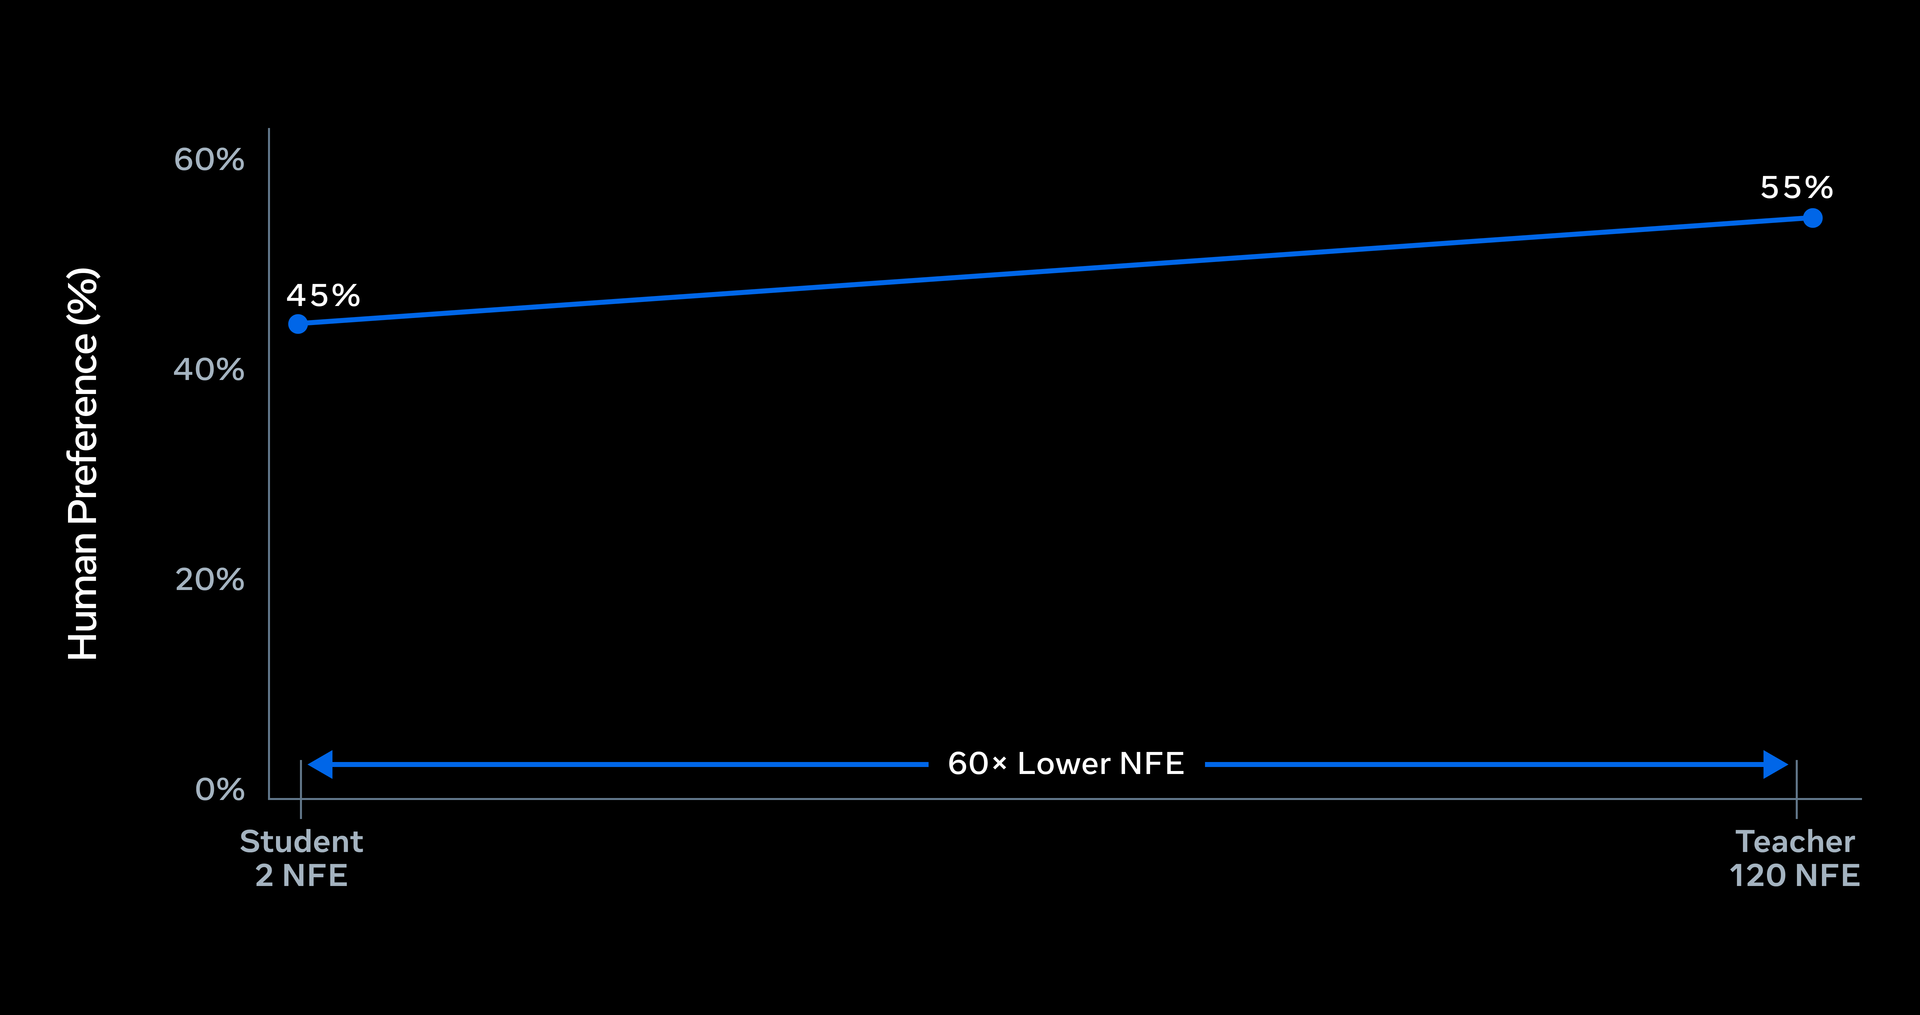
Distillation reduces inference from 120 to 2 neural function evaluations per chunk, a 60x reduction, while yielding a near-even split in overall preference.
State-of-the-Art Avatar Experiences
To understand how Muse Realtime Avatar performed in live conversation, we compared it with Runway Characters and HeyGen LiveAvatar, the two leading commercial avatar systems, using each product’s native live-call experience. Raters held two- to three-minute conversations with each system using matched avatar identities, then compared the experiences across visual quality, synchronization, character consistency, and mannerisms, among others. The chart below reports overall preference where raters more often preferred Muse Realtime Avatar.
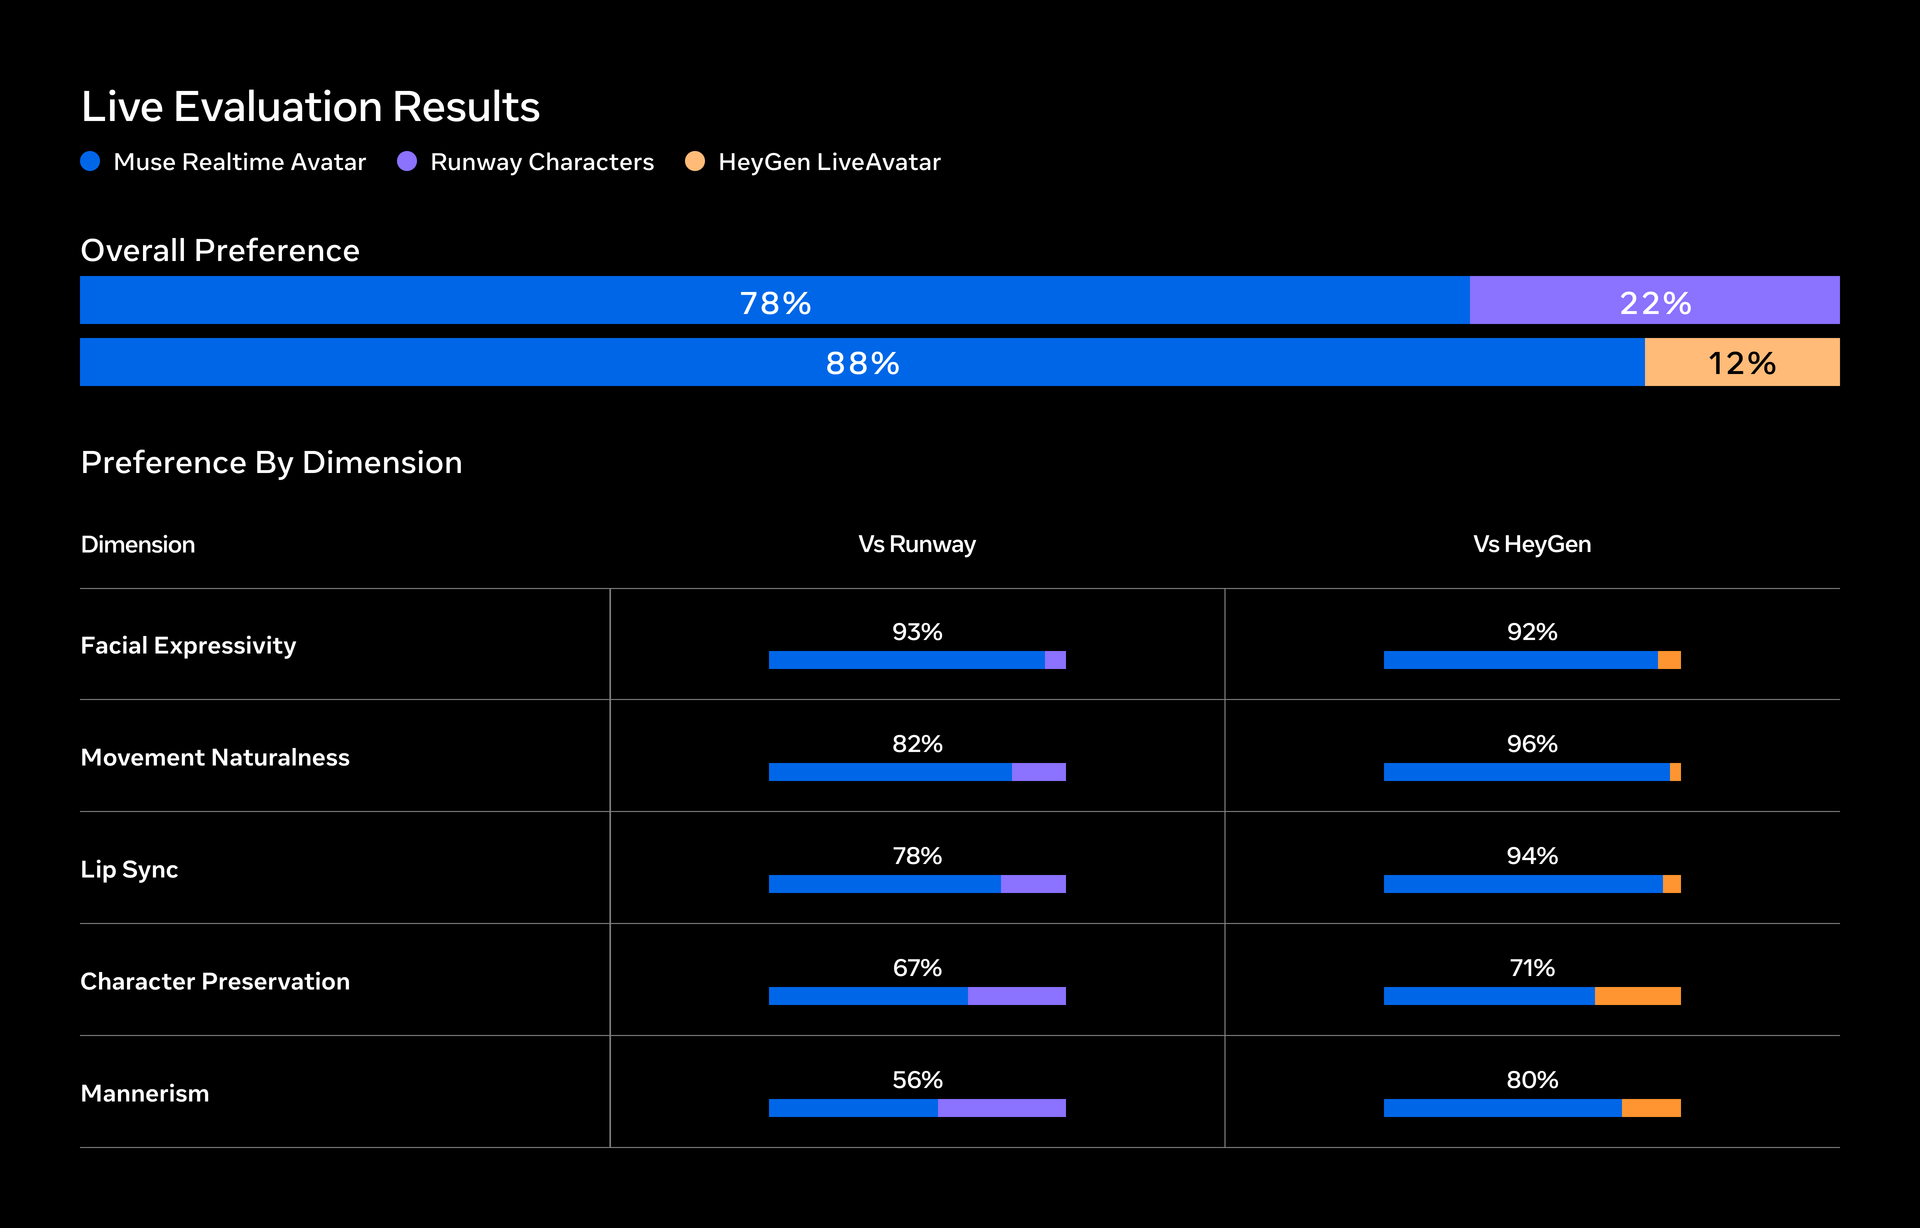
Raters preferred Muse Realtime Avatar overall and across every evaluated dimension. The mannerism comparison with Runway Characters was not statistically distinguishable from parity.
Serving at Subsecond Latency at Meta Scale
Muse Realtime Avatar continuously generates an avatar's video as a live conversation unfolds. Delivering that experience at Meta scale requires both interactive latency and high concurrency. To make this possible, we redesigned the real-time AI inference stack at Meta from the ground up and coupled this with an in-house custom engine built for highly optimized real-time video inference and serving.
Persistent KV caches with memory aware positional encodings allow us to smartly reuse context across chunks while decoding. Cache-aware routing and latency-aware dynamic batching efficiently distribute concurrent sessions. Four-bit quantization-aware training preserves quality at lower inference cost, while fused kernels and NVIDIA CUDA Graph capture reduce memory traffic and scheduling overhead. We collaborated with NVIDIA on a number of model optimizations to minimize the cost of the model’s forward pass. The entire system, including the underlying infrastructure, is optimized end-to-end to ensure a smooth user experience.
Muse Realtime Avatar streams 448x768 portrait video at 25 frames per second with approximately 870 ms of latency as measured from the end of a user’s turn to when they receive the first byte of the synchronized voice-and-video response. For a single session on a GB200, each generation step produces eight frames, corresponding to 320 ms of playback, in 20 ms, or an effective 2.5 ms of model time per frame.
The optimizations mentioned above coupled with smart orchestration across voice and video increase serving capacity by 8x relative to the two-step BF16 baseline, enabling 12 concurrent real-time sessions for the video generation on a single GB200.
Browse through conversations with Muse Realtime Avatar, delivered at interactive, subsecond latency.
Building Embodied AI Responsibly
We enforce strict safety requirements throughout the experience to reduce the risk of misuse and protect people. To make generated media traceable, Muse Realtime Avatar uses Meta Video Seal to embed a durable, invisible watermark throughout generated video without adding latency to the real-time experience. We’ll continue strengthening these protections as embodied AI evolves. All examples in this blog post illustrate model capability and do not all reflect avatars available in the Muse app. Muse is for users aged 18+.